Configure and Run Evaluations
Evaluation tasks save reusable configurations, including test sets, execution positions, models, and metrics. Each run creates a new execution record for reviewing its results.
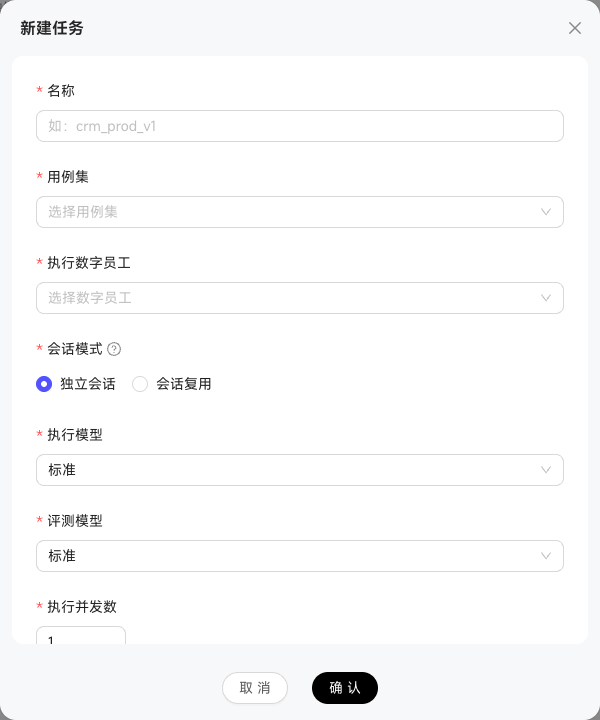
Enter a name and select the test set and execution position.
Independent Conversations starts a separate conversation per case to prevent interference. Conversation Reuse asks cases sequentially in one conversation, suitable for follow-up and multiround context testing.
Choose an execution model for the position's answers and an evaluation model for scoring. Execution concurrency controls simultaneous cases; evaluation concurrency controls simultaneous scoring. Higher values run faster but consume more resources.
All existing metrics are selected by default; deselect any you do not need. For recurring regression checks, enable Scheduling to trigger execution and evaluation at the chosen interval.
Task row actions include Execute (run without scoring) and Execute + Evaluate (run and then score). You can also edit or delete configurations.
Execution Records shows each run's status, progress, duration, and start time. The top summarizes total batches and counts for Running, Evaluating, Completed, and Failed. Open a record for its report. Completed records can be evaluated again.